Reinforcement Learning for Diverse Solutions
Offline Diversity Under Imitation Constraints
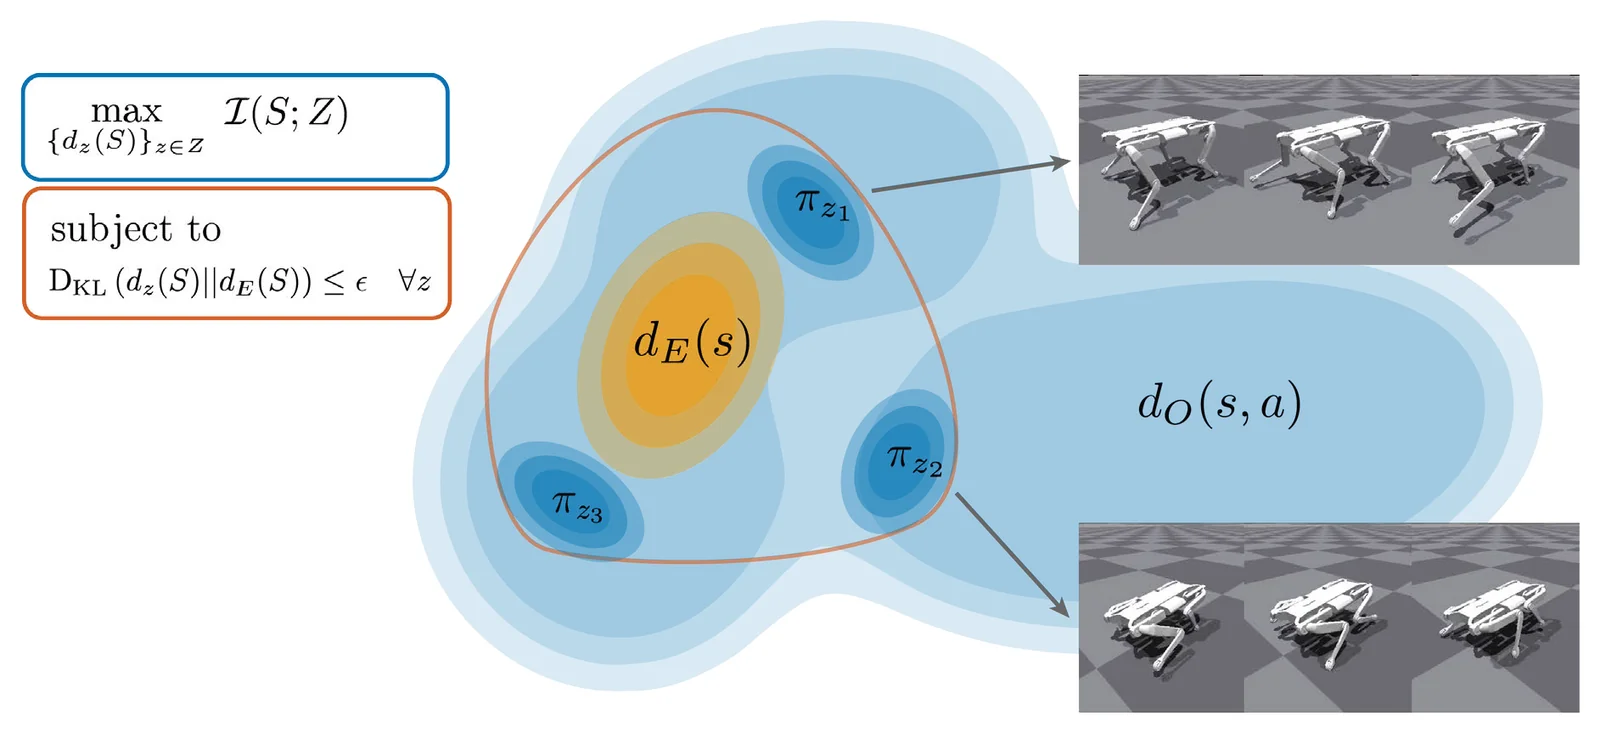
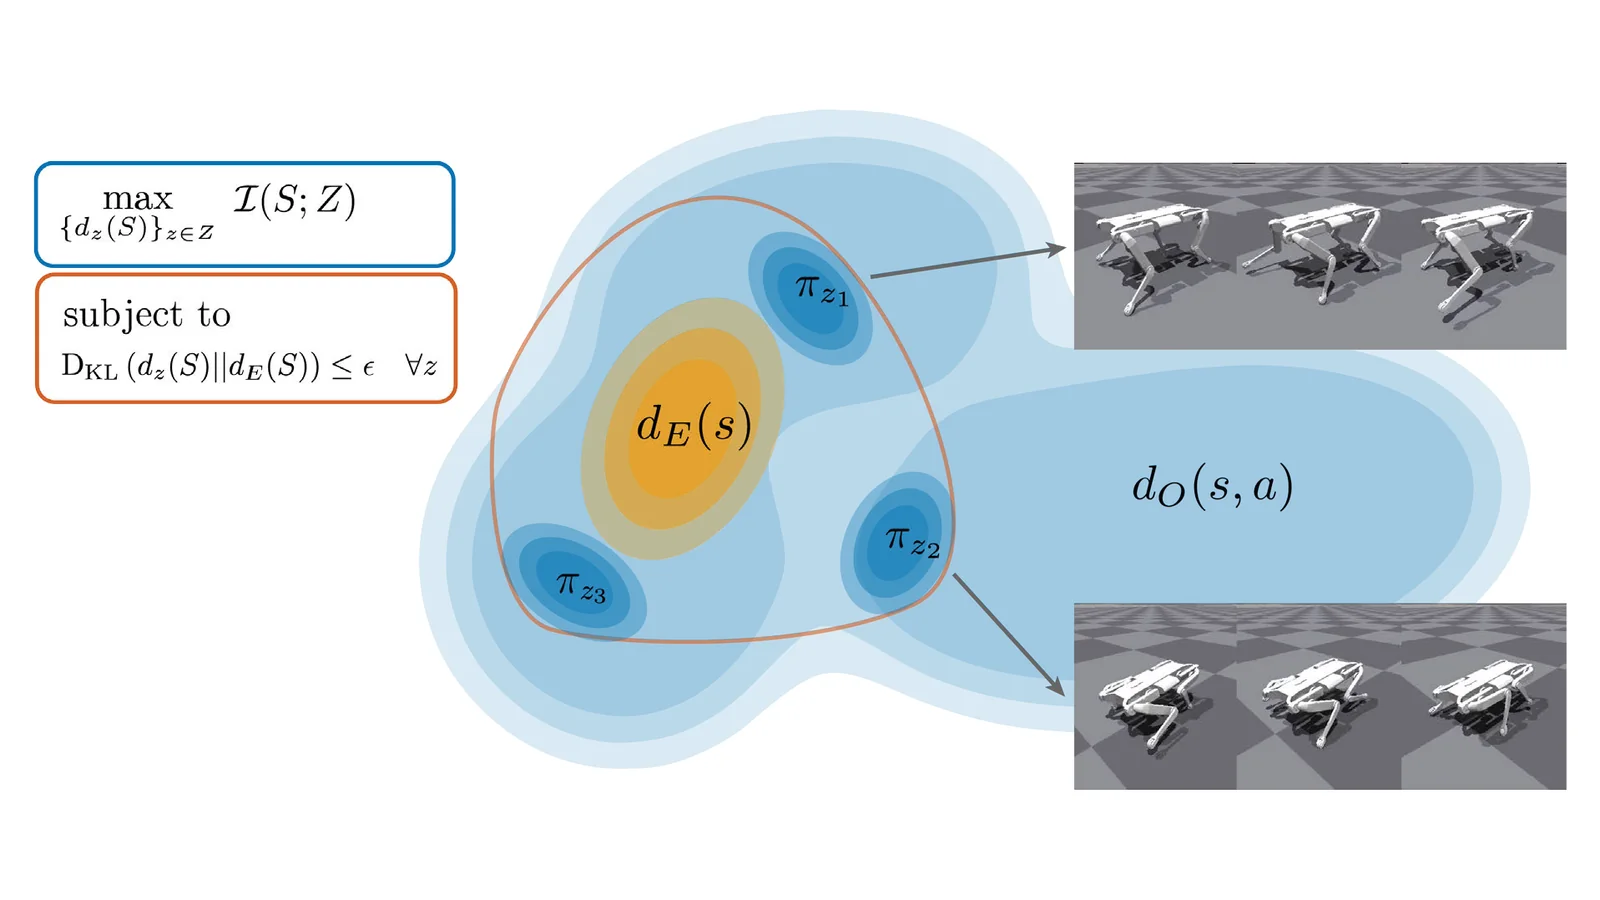
Our offline algorithm maximizes skill diversity under imitation constraints. It effectively performs on standard benchmarks and real robot data, showcased on a 12-DoF quadruped robot.
We study the offline setting, i.e., when only data from previous interactions are available and no further environmental interaction is possible. We propose the first principled offline method for maximizing skill diversity under imitation constraints. The method requires access to an explorative dataset of the environment and a few demonstrations of solving a task. Here, we focus on the challenging and practically relevant setting where the demonstrations are provided only in terms of visited states, i.e., without actions. To generate diversity, based on an information-theoretic objective, the method trains a skill discriminator.
The follow-up work eliminates the need to learn a skill discriminator by providing an offline estimator of the Van der Waals (VdW) distance. We also use Functional Reward Encoding to better handle non-stationary rewards, allowing for stable, efficient training and zero-shot recall of all skills encountered during training.
Publications
2026
2024